Longhorn 10257: show why a volume isn't ready PR not opened yet
UI half of longhorn 9968. Branch 10257-not-ready-message on your fork, one commit 4d4d10b on upstream master 0f560ca. Updated 2026-11-10.
Preview: http://13.60.211.184:30080 (this branch) and http://13.60.211.184:30081 (master), both against the longhorn dev cluster (Longhorn master-head). The test volume is lh10257-unsched.
What changes
- When a volume isn't ready for workloads, the UI used to guess the cause from the volume health: "Volume Faulted" if faulted, otherwise "Volume may be under maintenance or in the restore process."
- The manager now returns the real reason with each volume as
notReadyMessage(longhorn-manager PR 4937, merged 2026-06-30, also in 1.12.1). The CSI attach error carries the same text. - Both tooltips now read "Not ready for workload: <reason>", the same reason as the
volume … is not ready for workloads: <reason>error in the workload events. Plain "Not ready for workload" if the message is empty. - Three files, +8 / −4: one helper in
src/routes/volume/helper/index.js, used byVolumeList.jsanddetail/VolumeInfo.js.
Video
lh10257-unsched is a 100 Ti volume that no disk can hold, so no replica schedules: it's detached + faulted and can't attach. The clip points at the list icon and the detail row on master, then on this branch (36 s, URL band cropped).
Screenshots
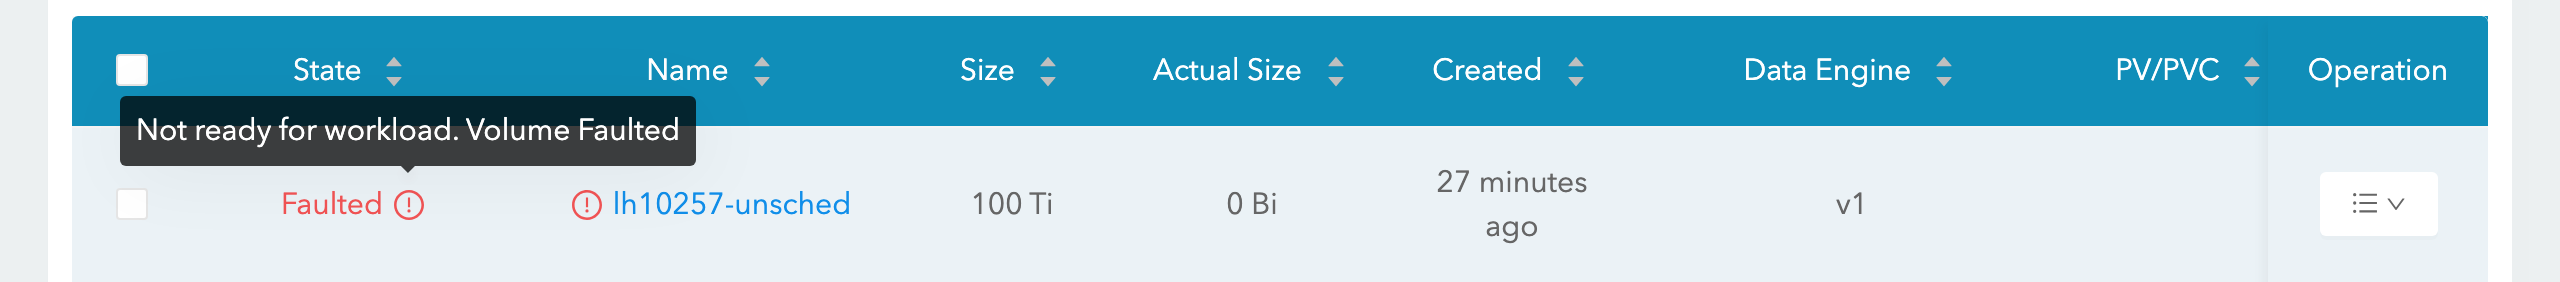
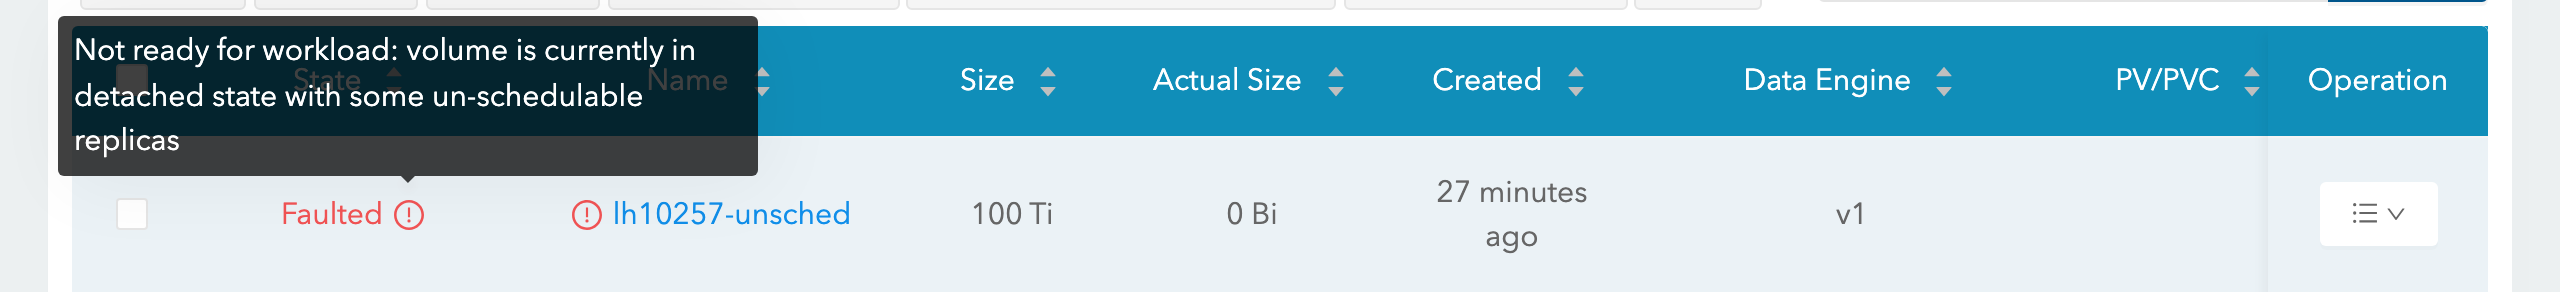
Volume list, State column
Volume details, "Ready for workload"


Where it shows
| Where | When it shows | master | This branch |
|---|---|---|---|
| Volume list, State column: the red ⓘ after the state | Shown only for attached + healthy, attached + degraded and detached + faulted (unchanged). | "Not ready for workload. Volume Faulted" or "Not ready for workload. Volume may be under maintenance or in the restore process." | "Not ready for workload: <reason>" |
| Volume details, "Ready for workload: Not Ready" | Whenever the volume isn't ready. | Same two guesses. | "Not ready for workload: <reason>" |
Either place, empty notReadyMessage (an older manager) | n/a | "Not ready for workload" |
What the tooltip can say now
The reasons the manager can return (types.IsVolumeReady, in the order it checks them):
| Reason | When | Here |
|---|---|---|
waiting for the volume to fully detach. current state: <state> | The volume was asked to detach (no node set) but hasn't reached detached yet. | Not tested (transient) |
volume is currently in detached state with some un-schedulable replicas | Detached, the Scheduled condition isn't True, and some replica has no node. | Tested: lh10257-unsched |
volume is faulted | Robustness is faulted: no usable replica. | Not tested (needs the webhook edit QA used) |
volume request cloning data but has not finished copying data | A clone whose copy hasn't finished. | Not tested (transient) |
volume requires restoration | A volume restored from a backup (or a DR volume) that still has to restore. | Not tested (no backup target on the cluster) |
What was checked
| Check | Result | |
|---|---|---|
| Field from the backend | GET /v1/volumes on the dev cluster (manager pr5332-local, master-head) returns notReadyMessage: empty on ready volumes, the reason on lh10257-unsched | ✓ |
| Volume list tooltip | master: "Not ready for workload. Volume Faulted"; this branch: "Not ready for workload: volume is currently in detached state with some un-schedulable replicas" | ✓ |
| Volume details tooltip | Same text as the list on each build | ✓ |
| Ready volumes | nrq-one details show "Ready"; the list shows one not-ready icon (only the test volume) | ✓ |
| Bundles | Only the branch bundle has notReadyMessage; only master has the old "maintenance or in the restore" text | ✓ |
| Lint | eslint clean on the 3 files. The repo-wide pre-commit hook still fails on upstream RestoreBackupModal.js, so the commit used --no-verify | ✓ |
| Commit | Signed, author marcelo.fukumoto@suse.com, GitHub shows verified | ✓ |
| Plain "volume is faulted" | Not reproduced live. Its text barely changes ("Volume Faulted" → "volume is faulted") | — |
| Unit tests | None: the repo has one test file and CI doesn't run jest | — |
Open items
| Item | Status |
|---|---|
| Open the PR | Waiting for you: ready for review (backend already merged) or draft. Then attach the clip and update the issue. |
| Rancher extension | rancher/longhorn-ui-extension shows the same guessed text (VolumeDetails.vue, VolumeWarnings.vue), but it reads the Volume CR, which has no notReadyMessage. A separate change; not mentioned in the PR, as on 13735. |
| List icon only in 3 state combos | A detached volume that isn't faulted (robustness unknown) gets no icon in the list, only on its details page. Unchanged here; showing it would also flash the icon while volumes detach. |
| Cleanup | Test volume lh10257-unsched and the two previews stay until the PR is done. |
The code
Full diff (3 files, +8 / −4)
diff --git a/src/routes/volume/VolumeList.js b/src/routes/volume/VolumeList.js
index ea5b1e9..e92128d 100755
--- a/src/routes/volume/VolumeList.js
+++ b/src/routes/volume/VolumeList.js
@@ -6,7 +6,7 @@ import classnames from 'classnames'
 import { LinkTo, EngineImageUpgradeTooltip, ReplicaHATooltip } from '../../components'
 import { formatMib } from '../../utils/formatter'
 import VolumeActions from './VolumeActions'
-import { isSchedulingFailure, getHealthState, needToWaitDone, extractImageVersion } from './helper/index'
+import { isSchedulingFailure, getHealthState, getNotReadyMessage, needToWaitDone, extractImageVersion } from './helper/index'
 import { sortTable, sortTableObject, sortTableByUTCDate, sortTableByPVC, sortTableActualSize, sortTableState, sortTableByTimestamp } from '../../utils/sort'
 import { setSortOrder } from '../../utils/store'
 import { statusUpgradingEngine } from '../../utils/status'
@@ -182,8 +182,7 @@ function list({
           let attachedNode = record.controllers && record.controllers[0] && record.controllers[0].hostId ? record.controllers[0].hostId : ''
           return item.hostId !== attachedNode
         })
-        let statusForWorkloadMessage = `Not ready for workload. ${record.robustness === 'faulted' ? 'Volume Faulted' : 'Volume may be under maintenance or in the restore process.'} `
-        let statusForWorkload = <Tooltip title={statusForWorkloadMessage}><Icon type="exclamation-circle" className="faulted" style={{ marginLeft: 5 }} /></Tooltip>
+        let statusForWorkload = <Tooltip title={getNotReadyMessage(record)}><Icon type="exclamation-circle" className="faulted" style={{ marginLeft: 5 }} /></Tooltip>
         let stateText = (() => {
           if (text.hyphenToHump() === 'attached' && record.robustness === 'healthy') {
             return (<div
diff --git a/src/routes/volume/detail/VolumeInfo.js b/src/routes/volume/detail/VolumeInfo.js
index 2d25988..80f2b32 100644
--- a/src/routes/volume/detail/VolumeInfo.js
+++ b/src/routes/volume/detail/VolumeInfo.js
@@ -7,6 +7,7 @@ import { formatMib } from '../../../utils/formatter'
 import {
   isSchedulingFailure,
   getHealthState,
+  getNotReadyMessage,
   needToWaitDone,
   frontends,
   extractImageVersion,
@@ -232,7 +233,7 @@ function VolumeInfo({ selectedVolume, snapshotModalState, engineImages, hosts, c
       </div>
       <div className={styles.row}>
         <span className={styles.label}> Ready for workload:</span>
-        {selectedVolume.ready ? <span className="healthy">Ready</span> : <Tooltip title={`Not ready for workload. ${selectedVolume.robustness === 'faulted' ? 'Volume Faulted' : 'Volume may be under maintenance or in the restore process.'} `}><span className="faulted">Not Ready</span></Tooltip>}
+        {selectedVolume.ready ? <span className="healthy">Ready</span> : <Tooltip title={getNotReadyMessage(selectedVolume)}><span className="faulted">Not Ready</span></Tooltip>}
       </div>
       <div className={styles.row}>
         <div className={styles.formItem} style={{ display: 'flex' }}>
diff --git a/src/routes/volume/helper/index.js b/src/routes/volume/helper/index.js
index f5180d9..764a740 100644
--- a/src/routes/volume/helper/index.js
+++ b/src/routes/volume/helper/index.js
@@ -768,6 +768,10 @@ export function getHealthState(state) {
   return state.toLowerCase() === 'unknown' ? 'unknown' : state.hyphenToHump()
 }

+export function getNotReadyMessage(volume) {
+  return volume.notReadyMessage ? `Not ready for workload: ${volume.notReadyMessage}` : 'Not ready for workload'
+}
+
 export function needToWaitDone(state, replicas) {
   return state === '' || state.endsWith('ing') || replicas.findIndex(item => item.mode.toLowerCase() === 'wo') > -1
 }
PR description draft
### What this PR does / why we need it

When a volume isn't ready for workloads, the volume list and the volume details page show a "Not ready for workload" tooltip, but the UI guessed the cause from the volume health: "Volume Faulted" for a faulted volume, and "Volume may be under maintenance or in the restore process." for anything else.

The manager now returns the real reason with each volume as `notReadyMessage` (https://github.com/longhorn/longhorn-manager/pull/4937). I show it in both tooltips, so they read `Not ready for workload: <reason>`, the same reason the CSI plugin puts in the attach error (`volume ... is not ready for workloads: <reason>`). If the message is empty, the tooltip just says "Not ready for workload".

For example, a volume too big for any disk is detached and faulted. On master the tooltip says "Volume Faulted". With this PR it says "volume is currently in detached state with some un-schedulable replicas".

### Issue

https://github.com/longhorn/longhorn/issues/10257

### Test Result

I tested against a Longhorn master-head cluster:

- A 100 Ti v1 volume that no disk can hold: master shows "Not ready for workload. Volume Faulted" in the volume list and on the details page. This PR shows "Not ready for workload: volume is currently in detached state with some un-schedulable replicas" in both.
- Ready volumes are unchanged: no icon in the list, and "Ready" on the details page.

Before (master), then after (this PR):

(the clip, uploaded once the PR exists)

### Additional documentation or context

UI only. The `notReadyMessage` field comes from the manager change above.
Reproduce the not-ready volume
curl -X POST -H 'Content-Type: application/json' $LONGHORN/v1/volumes -d '{"name":"lh10257-unsched","size":"109951162777600","numberOfReplicas":3,"dataEngine":"v1","frontend":"blockdev","accessMode":"rwo"}'
# 100 Ti: no disk can hold a replica → detached + faulted, ready=false
# A 4-replica volume on 3 nodes doesn't work: allow-volume-creation-with-degraded-availability keeps Scheduled True.